
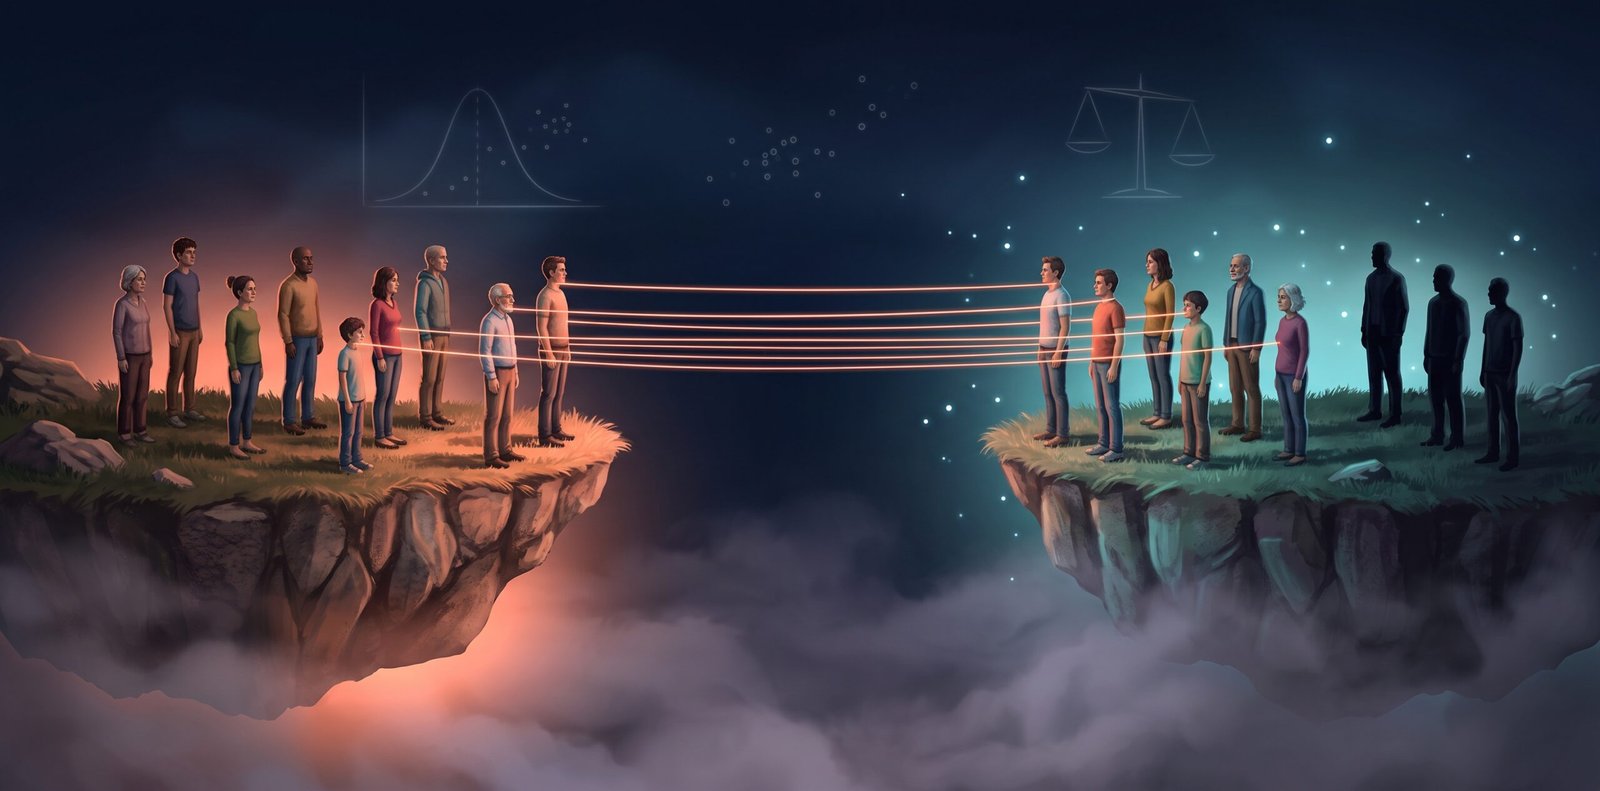
Some of the most important questions in health will never get a randomized trial. Nobody will randomize people to decades of shift work, a caregiving role or a new tax on sugary drinks. Yet policymakers still need causal answers, and observational research is often the only evidence on the table. Regulators now weigh real-world evidence from health records and insurance claims when they judge medical products.8
Propensity score matching (PSM) is one of the most widely used tools for turning those data into causal claims. Used rigorously, it approximates the trial you could never run.5 Used carelessly, it gives confident answers to the wrong question. Here’s what separates the two.
| What you’ll learn | What you’ll be able to do |
|---|---|
| How PSM builds a trial-like comparison | Explain what matching can and cannot balance |
| How to check whether matching worked | Read and judge a covariate balance table |
| How to handle unmeasured confounders | Report a sensitivity analysis such as the E-value |
How Propensity Score Matching Mimics a Randomized Trial
Rosenbaum and Rubin defined the propensity score as each person’s probability of receiving treatment, given their observed baseline characteristics.1 Their key result is elegant. People with the same score share, on average, the same distribution of those measured covariates, whether or not they were treated. So instead of matching on 30 variables at once, you match on one number.
Think of it as a seating chart. Randomization shuffles everyone into two rooms, so the rooms look alike on everything, measured or not. Matching seats each treated person beside an untreated person with a near-identical profile. The rooms end up alike, but only on the traits written on the chart.2 Matching also changes the question: most matched designs estimate the effect in people who were treated, so state your target estimand before you match.6
Matching balances what you measured. It can’t touch what you didn’t.
Design First, Then Check Covariate Balance
For causality claims, Rubin’s rule is simple and often ignored: build the matched groups before you look at any outcome data.7 That keeps the design honest, because you can’t tune the match until the result looks the way you hoped. Treat it like a trial protocol and write it down first.
Next, prove that propensity score matching worked. A t-test p-value tells you little here, since it rises and falls with sample size. Compare groups with standardized differences, variance ratios and plots of each covariate’s distribution instead.3 Comparing the propensity score itself across groups isn’t enough, because that comparison says almost nothing about covariate balance.3
| Diagnostic | What it checks | Common benchmark |
|---|---|---|
| Standardized mean difference | Difference in each covariate’s mean or proportion, in standard deviation units | Below 0.1 |
| Variance ratio | Whether continuous covariates have similar spread in both groups | Close to 1 |
| Distribution plots | The whole shape of each covariate, not just its average | Clear overlap across the range |
A PSM study is only as credible as the balance table it reports.
Unmeasured Confounders and Real-World Evidence
No match can balance a confounder nobody recorded. The honest response is to measure how strong that hidden confounder would need to be. The E-value does exactly this. It gives the minimum risk ratio an unmeasured confounder would need with both treatment and outcome to explain away the result.4
Does rigor pay off? When researchers emulated 32 clinical trials with claims data and propensity score matching, the results tracked the trials closely (r = 0.82).10 Agreement rose to 0.93 when researchers could closely emulate the trial design and fell to 0.53 when they couldn’t.10 An earlier emulation of 10 cardiovascular trials told a similar story.9
Close emulation of the trial you wish you had is what earns the causal claim.
Conclusion
Propensity score matching doesn’t create causality from data. It creates a fair comparison. You earn the causal claim by showing your work: fix the design before seeing outcomes, prove covariate balance and report how much hidden confounding would overturn the result. Do that, and observational research becomes real-world evidence that can guide policy.8,10
“Observational studies can and should be designed to approximate randomized experiments as closely as possible.”
Donald B. Rubin, Statistics in Medicine, 20077
Reviewing a PSM study this week? Before you trust it, ask for three things: the prespecified design, the balance table and the E-value.
Useful Resources
- FDA: Real-World Evidence: How the US regulator defines real-world data and evidence, with its current guidance documents.
- Austin (2011), free full text: A clear methods primer on all four propensity score approaches, including balance diagnostics.
- Stuart (2010), free full text: The standard review of matching methods, with practical guidance on choosing among them.
- Hernán and Robins (2016), free full text: The target trial framework for designing observational analyses of big data.
FAQs
Is propensity score matching better than regression adjustment?
Not automatically. Both rely on the same assumption of no unmeasured confounding, but matching separates design from analysis and makes balance visible in a table. Austin (2011) compares the approaches directly.
What standardized difference counts as balanced?
A common benchmark is below 0.1 for every covariate, checked alongside variance ratios and plots. Austin (2009) explains why these diagnostics beat significance tests.
Can PSM prove causality?
No single method can. PSM makes a causal claim credible only if its assumptions hold, which is why the E-value should accompany the estimate.
How does PSM relate to target trial emulation?
Target trial emulation is the design framework, and PSM is one way to adjust for confounding within it. Hernán and Robins (2016) set out the framework.
Where does real-world evidence fit in policy?
Regulators increasingly use it to support decisions about medical products. The FDA real-world evidence program describes how.
Future Blog Topics
| Topic | Why it matters |
|---|---|
| Matching or weighting? Choosing a propensity score method | Inverse probability weighting keeps your full sample but brings its own trade-offs |
| Target trial emulation, step by step | A design checklist that prevents the most common observational biases |
| Reading an E-value like a reviewer | Turns a sensitivity analysis into a judgment you can defend |
Leave a Reply